The rapid evolution of Large Language Models (LLMs) has fundamentally shifted how developers approach machine learning workflows. While traditional machine learning relies on optimizing parameters like learning rates, tree depth, or regularization strengths, the advent of generative AI has introduced a new, critical variable: the prompt. In this technical analysis, we explore a methodological framework for treating prompt templates as tunable hyperparameters, utilizing the industry-standard scikit-learn library to automate the selection of the most effective linguistic instructions for zero-shot text classification.
The Evolution of Model Optimization
For over a decade, data scientists have relied on grid search and random search to navigate the complex hyperparameter spaces of models such as Support Vector Machines (SVMs), Gradient Boosting machines, and Neural Networks. These systematic search algorithms evaluate a discrete set of configurations against a validation set to identify the "sweet spot" that maximizes objective metrics such as accuracy, F1-score, or area under the receiver operating characteristic curve (AUC-ROC).
As organizations transition from training custom models to deploying pre-trained LLMs, the primary challenge has shifted from architecture design to "prompt engineering." Often, this remains a manual, iterative process based on intuition rather than empirical evidence. By formalizing prompts as hyperparameters, engineers can move from subjective guesswork to a data-driven paradigm where the "best" instruction is selected based on rigorous cross-validation.
Chronology of the Integration
The integration of LLMs into standard machine learning pipelines represents a convergence of two distinct schools of thought: the probabilistic nature of transformer-based generation and the structured, deterministic workflows of traditional scikit-learn pipelines.
- Phase I: The Encapsulation. The first step in this workflow is creating a custom wrapper. By inheriting from
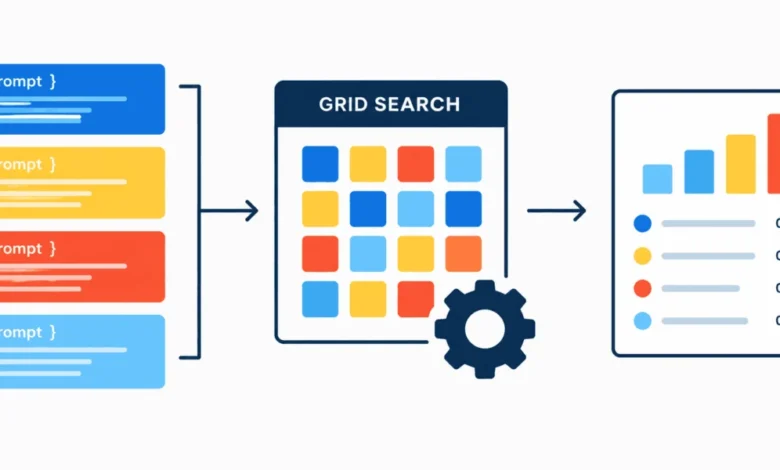
BaseEstimatorandClassifierMixin, we force the LLM to interface with standard scikit-learn methods—fit()andpredict(). This allows the model to act as a black-box classifier, where the "fitting" process is a placeholder and the "prediction" process involves passing a prompt through the model to retrieve a structured output. - Phase II: The Search Space Definition. Once the wrapper is established, the prompt templates are treated as categorical variables within a
param_grid. This allows the developer to test variations in tone, instruction length, and logical structure simultaneously. - Phase III: Cross-Validation. Using
GridSearchCV, the system iterates through each template, evaluating it against the specified data folds. The result is a statistically grounded selection that minimizes bias and overfitting to a single, potentially suboptimal prompt.
Technical Implementation and Workflow
To implement this, one must first ensure the environment is configured to handle the memory requirements of local LLM inference. Utilizing lightweight, instruction-tuned models such as Qwen/Qwen2.5-0.5B-Instruct provides an accessible entry point for testing these workflows without the need for massive GPU clusters.
The process begins by defining a class, ZeroShotPromptClassifier, which serves as the interface between the raw input text and the LLM’s generation engine. The critical logic lies in the predict method, where the template is formatted with the input data, converted into a standardized chat-message format, and submitted to the model. A crucial refinement in this approach is the strict enforcement of output constraints; by limiting max_new_tokens and parsing the response for expected keywords like "positive" or "negative," the developer can effectively map generative output to discrete class labels.
The following code illustrates the initialization of this process:
import numpy as np
from sklearn.base import BaseEstimator, ClassifierMixin
from sklearn.model_selection import GridSearchCV
from transformers import pipeline

# Initializing the inference pipeline
generator = pipeline("text-generation", model="Qwen/Qwen2.5-0.5B-Instruct")

class ZeroShotPromptClassifier(BaseEstimator, ClassifierMixin):
    def __init__(self, generator, prompt_template="Classify as positive or negative: text"):
        self.generator = generator
        self.prompt_template = prompt_template

    def fit(self, X, y=None):
        return self

    def predict(self, X):
        predictions = []
        for text in X:
            prompt = self.prompt_template.format(text=text)
            messages = ["role": "user", "content": prompt]
            output = self.generator(messages, max_new_tokens=5)
            reply = output[0]['generated_text'][-1]['content'].strip().lower()

            if "positive" in reply:
                predictions.append("positive")
            elif "negative" in reply:
                predictions.append("negative")
            else:
                predictions.append("unknown")
        return np.array(predictions)
Data-Driven Prompt Selection
In empirical testing, the difference between a high-performing prompt and a mediocre one can be significant. By defining a grid of variations, such as:
- "Classify as positive or negative: text"
- "Is the sentiment positive or negative? Text: text"
- "Analyze this review. Output ‘positive’ or ‘negative’: text"
The GridSearchCV object performs a systematic sweep. In small-scale validation, the third template often yields higher accuracy because it provides explicit instructions regarding the output format, which helps the model avoid verbose explanations and stick to the requested classification labels.
Broader Implications for AI Engineering
This systematic approach carries profound implications for the industry. First, it addresses the "reproducibility crisis" in prompt engineering. When prompts are documented as hyperparameter configurations in a Git-controlled param_grid, the experimental process becomes transparent and reproducible.
Second, it allows for "prompt tuning" across diverse domains. A company may find that a specific, highly technical prompt works best for classifying internal support tickets, while a more casual, conversational prompt is more effective for social media sentiment analysis. By offloading this discovery to an automated search algorithm, teams can save hundreds of hours of manual testing.
Finally, this methodology provides a pathway to cost-optimization. As organizations scale their use of paid APIs, finding the shortest, most effective prompt—which consumes fewer tokens—becomes a matter of operational efficiency. A prompt that is optimized for accuracy and brevity directly translates to lower latency and reduced expenditure.
Challenges and Future Considerations
While the benefits of this approach are clear, developers must remain cognizant of the constraints. First, the size of the search space is limited by the computational budget. Testing 50 different prompt variations against a large dataset can be time-consuming and expensive. Consequently, developers should utilize this technique on representative subsets of their data before scaling to full production environments.
Additionally, this method assumes that the prompt template is the primary lever for performance. In practice, factors such as temperature, top-p sampling, and system instructions also play a vital role. Future iterations of this framework could extend the param_grid to include these model-specific parameters, allowing for a multidimensional optimization of the entire inference configuration.
Ultimately, treating prompts as hyperparameters represents a maturing of the AI field. It signals a move away from the "black box" era of prompt engineering toward a structured, engineering-focused discipline that prioritizes empirical validation over speculative adjustment. By leveraging the tools already provided by the machine learning ecosystem, developers can ensure that their AI deployments are not only functional but also optimized for the specific nuances of their unique datasets.