caching
-
Machine Learning
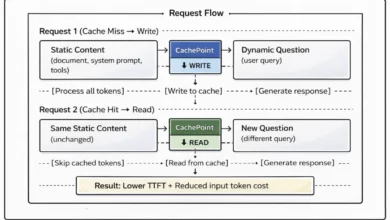
Amazon Bedrock Prompt Caching Guide Optimizing Costs and Latency with the Converse API
Enterprise adoption of generative artificial intelligence has accelerated dramatically over recent years, but organizations increasingly grapple with the escalating operational…
Read More » -
Machine Learning

Amazon Web Services Introduces Model Caching for Amazon SageMaker Inference on HyperPod to Eliminate Cold Start Latencies for Large Language Models
The deployment of massive large language models (LLMs) for enterprise production environments has long faced a significant operational hurdle: the…
Read More »