3 Ways to Optimize Small Language Models for Narrow Automation: Leveraging Key-Value Cache for Prefix Reuse

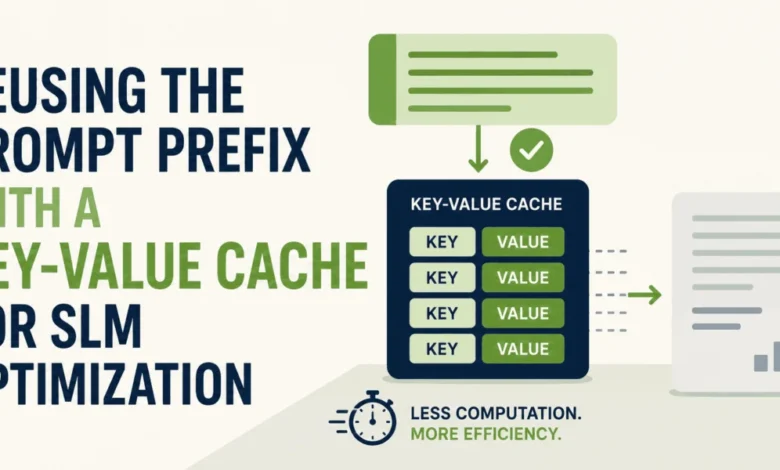
The deployment of Small Language Models (SLMs) in production environments has become a focal point for organizations seeking to balance computational efficiency with high-performance natural language processing. As enterprises shift toward narrow automation tasks—such as customer support ticket classification, automated email routing, and data extraction—the limitations of traditional, "full-prompt" inference cycles have become increasingly apparent. In a continuing series on optimizing these compact models, the second installment focuses on a critical architectural efficiency: the reuse of prompt prefixes via key-value (KV) caching. By minimizing redundant computational overhead, developers can achieve significant latency reductions, making SLMs a robust alternative to larger, resource-intensive models.
The Computational Overhead of Static Prompting
In a standard inference scenario, a language model treats every input request as a discrete, independent event. When processing a series of customer support tickets, a typical system submits a prompt containing a system instruction, a taxonomy of categories, and several few-shot examples, followed by the specific ticket text. In most narrow automation workflows, the instructions and examples remain static across thousands of calls.
Under the traditional approach, the model recomputes the key and value vectors for these static tokens during every single inference cycle. For an instruction block spanning several hundred tokens, this represents a substantial waste of GPU or NPU cycles. Because Transformer architectures compute these vectors based solely on preceding tokens, the calculations for a fixed prefix are identical for every ticket processed. Recognizing this redundancy allows developers to shift from a "full-encode" paradigm to a "prefix-cached" approach, where the system pre-computes the static instructions once and retains them in memory, processing only the variable portion of the prompt during each subsequent iteration.
Chronology of Optimization: Moving Beyond Naive Inference
The progression of SLM optimization has moved rapidly from simple model distillation to sophisticated runtime techniques. In the initial phase, researchers focused on reducing the parameter count—the primary driver of model size—to allow models like Qwen2.5-0.5B to run on edge hardware, such as the M2 Macbook Air.
Following the successful implementation of constrained output space—a technique that restricts the model to specific, valid tokens to improve accuracy and speed—the current focus has shifted to the "pre-fill" phase of inference. By implementing the KV cache, the system effectively "warms up" the model with the static context. Once the model has processed the system instructions and stored the internal states (keys and values) in a DynamicCache object, the computational cost per ticket is reduced to the processing of the new, dynamic input.
In controlled benchmarks utilizing the Qwen2.5-0.5B-Instruct model, the performance delta between naive and cached inference is stark. In a test run of 600 records, the naive approach required approximately 184.85 seconds to complete. By contrast, the implementation of prefix caching reduced the total runtime to 80.07 seconds—a performance gain of approximately 57%. This translates to an average reduction from 308.1 milliseconds per ticket to 133.5 milliseconds, a critical improvement for high-throughput automated systems.
Technical Implementation and Data Integrity
To ensure the validity of this optimization, the "token-clean" nature of the prompt split is paramount. Developers must ensure that the concatenation of the cached prefix and the dynamic suffix results in the exact same tokenization sequence as a monolithic prompt. If the boundary between the prefix and the suffix results in different token IDs due to sub-word splitting, the model’s internal states will diverge, leading to degraded classification accuracy.
The implementation relies on the Hugging Face transformers library, specifically utilizing the DynamicCache class. By passing the past_key_values argument during the forward pass, the model skips the re-encoding of the instruction block. Furthermore, the use of a cache_position tensor allows the model to correctly identify where the new, dynamic tokens sit in the attention matrix relative to the pre-existing static context. This precise alignment ensures that the model maintains its predictive accuracy while drastically reducing latency.
Industry Implications for Narrow Automation
The implications of these findings for the broader AI industry are significant. For years, the prevailing narrative has been that high-quality NLP requires massive, parameter-dense models. However, these benchmarks demonstrate that with intelligent system-level optimizations, small models can perform effectively for domain-specific tasks.
- Energy Efficiency: By reducing the total number of operations per inference, organizations can lower their carbon footprint and electricity costs, particularly when operating at scale.
- Latency Reduction: In customer service environments, every millisecond counts. Moving from ~300ms to ~130ms per request allows for real-time responsiveness that can be critical in high-pressure support environments.
- Hardware Accessibility: This optimization makes it possible to run sophisticated, reliable automation on consumer-grade hardware or edge devices, removing the necessity for expensive, high-bandwidth GPU clusters for simple classification tasks.
Expert Perspective and Future Directions
Industry observers note that while prefix caching is a well-understood concept in long-context modeling, its application to narrow automation is often overlooked by developers focused solely on model training. Matthew Mayo, a lead researcher in the field of data science and machine learning, emphasizes that the bottleneck for many production AI systems is not the model’s size, but the inefficiency of the surrounding code. "A small language model becomes a practical production choice once the code around it stops treating every call as an isolated event," Mayo noted. "Once the loop recognizes the redundancy in the prompt structure, the SLM transitions from being a compromise to being the obvious, high-efficiency choice."
The success of this strategy suggests that future developments will likely focus on "prompt-agnostic" caching, where the system automatically identifies static segments of user input and caches them without requiring manual prompt-splitting by the developer. This would further lower the barrier to entry for integrating SLMs into legacy business applications.
Challenges and Limitations
Despite the efficiency gains, prefix caching is not without its trade-offs. The primary limitation is the requirement for static input; the technique is only effective when the initial tokens of a prompt do not change. If a prompt includes real-time, frequently changing data at the very beginning of the string, the cache must be invalidated and recomputed, which can negate the performance benefits. Furthermore, developers must account for the memory overhead of maintaining these cache states. While the memory cost for a 0.5B parameter model is manageable on an M2 Macbook Air, scaling this to thousands of concurrent users in a server environment requires careful management of RAM allocation and cache eviction policies.
Conclusion: The Path Toward Efficient AI
As the industry moves away from the "bigger is always better" mentality, the focus on optimizing SLMs for narrow tasks represents a maturing of the AI landscape. Techniques such as prefix caching and constrained output space demonstrate that significant performance improvements are available through architectural refinement rather than just parameter expansion. For organizations looking to deploy robust, cost-effective automation solutions, the evidence is clear: by treating the static elements of prompt engineering as a pre-computable resource, developers can unlock the full potential of smaller, more nimble language models. The move toward this granular level of optimization is not merely a technical preference; it is a necessary step toward the sustainable, efficient, and reliable deployment of artificial intelligence in the real world.