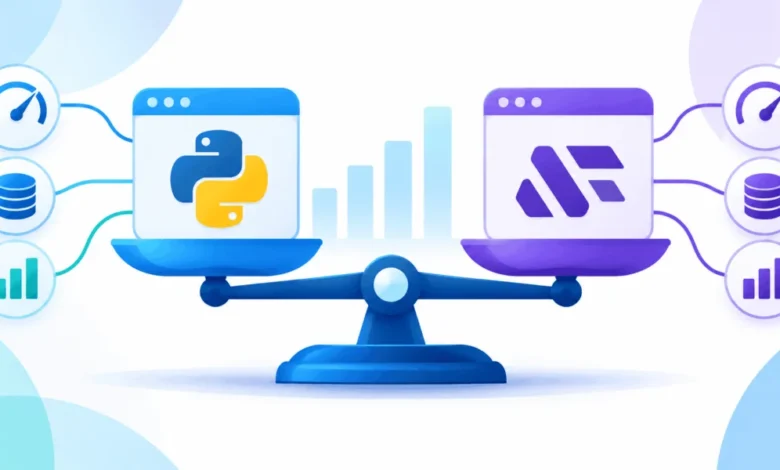
The rapid evolution of Large Language Models (LLMs) has forced developers to confront a critical architectural decision: whether to deploy models locally to ensure data sovereignty and control, or to leverage cloud-based infrastructure for superior computational performance and reduced operational overhead. This transition has led to the emergence of specialized Python frameworks that bridge the gap between traditional machine learning workflows and generative AI. Specifically, the integration of Scikit-Ollama and Scikit-LLM into standard Scikit-Learn pipelines has provided a standardized methodology for developers to perform side-by-side benchmarking. By utilizing these tools, engineers can quantify the tradeoffs between local inference—often hampered by hardware constraints—and cloud-based API inference, which offers rapid token generation at the cost of network dependency and potential privacy concerns.
The Shift Toward Standardized LLM Benchmarking
For years, machine learning engineers relied on established libraries like Scikit-Learn for classification tasks. However, the rise of LLMs introduced a new paradigm of "zero-shot" classification, where models categorize text without prior training on specific datasets. Bridging the gap between the rigid, predictable API of Scikit-Learn and the stochastic, often slow nature of LLMs is essential for production-grade applications.
The recent introduction of Scikit-Ollama and the expansion of Scikit-LLM to support third-party endpoints, such as those provided by Groq, represents a milestone in developer tooling. These libraries allow practitioners to treat complex LLMs as drop-in replacements for traditional classifiers. The fundamental question addressed by this benchmarking approach is not just which model is "smarter," but which architecture—local or cloud—best serves the latency, cost, and accuracy requirements of specific enterprise use cases.
Environmental Setup and Methodological Framework
To conduct a fair, reproducible evaluation, developers must establish a consistent testing environment. The methodology requires the installation of the Ollama engine for local model orchestration and the configuration of API wrappers for cloud services.
The setup process involves three distinct phases:
- Library Orchestration: Installing the necessary wrappers to ensure compatibility with Scikit-Learn’s
.fit()and.predict()methods. - Infrastructure Initialization: Launching the Ollama server to manage local model memory and weights, and configuring environment variables to securely handle API keys for cloud providers.
- The Universal Benchmark Function: Implementing a centralized helper function to ensure that metrics—specifically execution time, accuracy scores, and cost—are calculated identically for both the local and cloud-based models.
By using a helper function, developers eliminate the variance that typically occurs when measuring performance across disparate codebases. This approach ensures that the "time elapsed" metric reflects the true round-trip latency of the inference engine, rather than overhead from the Python application layer.
Scenario 1: The Case for Local Inference (Scikit-Ollama)
Local inference via Ollama utilizes the user’s hardware—be it a high-end GPU or a CPU-based system—to process data. When deploying models like Llama 3 locally, the primary advantage is the total absence of per-token costs and the assurance that sensitive data never leaves the local machine.
In controlled tests, local inference often exhibits higher latency due to the limitations of local hardware. For instance, in a zero-shot classification task, a local model might take significantly longer to generate a response than its cloud counterpart. However, for organizations operating in sectors with strict data residency requirements—such as finance or healthcare—the "latency penalty" is frequently viewed as a necessary trade-off for security. The use of Scikit-Ollama facilitates this by abstracting the complexities of model loading, allowing developers to focus on the classification output rather than the underlying infrastructure management.
Scenario 2: The Efficiency of Cloud-Backed Inference (Groq)
The alternative—cloud-backed inference—leverages specialized hardware, such as Groq’s Language Processing Units (LPUs), which are designed specifically for high-speed LLM execution. By routing Scikit-LLM requests through these specialized endpoints, developers can achieve sub-second latency that is rarely possible on consumer-grade hardware.
The integration of Scikit-LLM with Groq’s API demonstrates the power of custom URL routing. By configuring the ZeroShotGPTClassifier to point to a Groq endpoint, developers can access massive models that would otherwise be impossible to run on local machines. In benchmark testing, cloud-backed models consistently outperform local models in terms of speed, often by a factor of 20 or more. Furthermore, the accuracy of these models, when using advanced architectures like GPT-OSS-20B, often proves superior for complex, nuanced categorization tasks.
Comparative Analysis of Performance Metrics
When analyzing the performance data, three key metrics emerge:
- Latency: Local models are bound by the user’s hardware. On a standard development environment, a local model may take over 80 seconds to process a batch of queries, whereas an LPU-accelerated cloud model can achieve the same result in roughly 2 seconds. This delta is critical for real-time applications, such as chatbots or live sentiment analysis.
- Accuracy: While both approaches can achieve high accuracy on small datasets, cloud models benefit from larger parameter counts and more extensive training, leading to more consistent performance on edge cases.
- Cost: As of the current market cycle, the "free tier" of many API providers makes cost a neutral factor for small-scale projects. However, as projects scale to millions of requests, the cost of cloud inference becomes a significant operational expenditure, while local inference—though expensive in terms of hardware depreciation and power consumption—offers a fixed-cost model.
Broader Implications for AI Development
The ability to swap between local and cloud providers with minimal code changes—thanks to the standardized interfaces provided by Scikit-Ollama and Scikit-LLM—represents a maturing of the AI development ecosystem. This "vendor-agnostic" approach allows companies to develop their application logic once and decide on the deployment strategy based on real-time data needs.
If an application requires low latency for millions of users, the cloud remains the primary choice. If the application handles highly sensitive proprietary data, local inference is the clear winner. The benchmark results suggest that we are entering an era where the infrastructure choice is a tactical decision rather than a permanent architectural constraint.
Future Outlook and Technical Evolution
Looking forward, the integration of these tools into standard machine learning workflows is expected to accelerate. As open-source models like Llama 3 continue to narrow the performance gap with proprietary models, the barrier to entry for local, private, and secure AI will continue to lower. Simultaneously, the aggressive pricing and high-speed hardware being introduced by cloud-native companies like Groq are making the "Cloud vs. Local" debate more nuanced.
For the developer, the takeaway is clear: building a benchmarking pipeline is no longer an optional optimization—it is a foundational requirement. By implementing the techniques outlined, engineering teams can make data-driven decisions that balance the competing demands of cost, speed, and privacy, ensuring that their AI applications remain robust, scalable, and secure in an increasingly complex technical landscape.