The rapid integration of Large Language Models (LLMs) into enterprise workflows has created a significant divide between casual users and technical practitioners. As businesses move from experimental chatbots to automated operational pipelines, the terminology surrounding model interaction has become increasingly muddied. A critical distinction has emerged in the field: the difference between prompt engineering—the process of designing a prompt from scratch—and prompt optimization, which involves the iterative refinement of existing instructions to maximize reliability and accuracy. For organizations currently struggling with "hallucinations" or inconsistent data extraction, the solution rarely lies in replacing the underlying model, but rather in implementing rigorous, evidence-based optimization strategies that move beyond mere trial and error.
The Problem of Ambiguity in Automated Workflows
The necessity for precision is best illustrated by the processing of unstructured meeting data. Consider a scenario involving a three-person team discussing a checkout redesign, a billing migration, and support ticket management. In this transcript, several linguistic traps are present: a task is reassigned from one participant to another, a secondary requirement is folded into an existing assignment, and a critical operational triage task is left without an owner.
When a generic prompt is used—such as "Extract the action items from this meeting"—the LLM often yields a fluent but inaccurate summary. It may attribute the mobile review to the first speaker mentioned, ignore the tablet-breakpoint update, or fabricate an owner for the unassigned support queue task. In a production environment, these errors are not merely stylistic; they represent failures in business logic that can lead to missed deadlines and systemic operational bottlenecks.
Strategy 1: Mandating Structured Output via Schemas
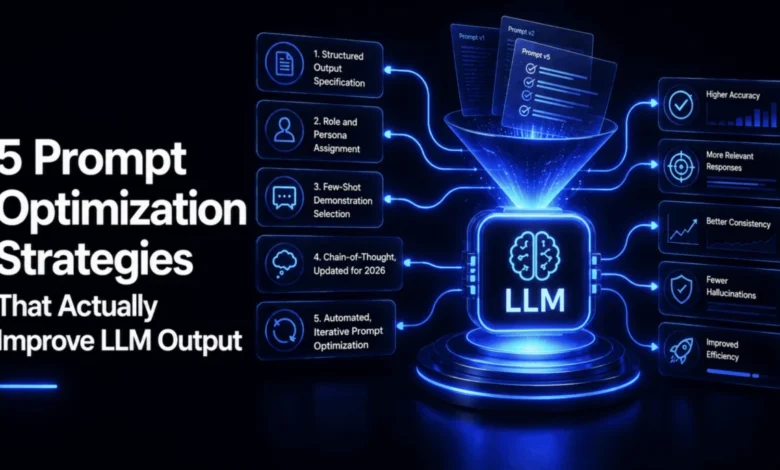
The most significant hurdle for LLM integration is the unpredictability of natural language output. When a model returns prose, it requires a human to interpret or a secondary process to parse, both of which introduce risk. Industry standards are shifting toward the use of programmatic schemas, such as Pydantic in Python, to enforce data integrity.
By defining a strict schema—requiring fields for "owner," "task," and "due date"—developers shift the model’s role from a conversationalist to a data provider. Testing demonstrates that while a vague prompt might result in a 100% failure rate for automated parsing, a schema-bound request forces the model to conform to rigid, machine-readable JSON formats. This transition from "text generation" to "data extraction" is the fundamental prerequisite for reliable downstream processing.
Strategy 2: Role-Based Priming and Persona Adoption
LLMs operate on probabilistic weights derived from vast datasets. By assigning a specific persona—such as a "meticulous executive assistant"—the user activates a more specific subset of the model’s latent knowledge. This is not a superficial stylistic choice; it is a mechanism for narrowing the model’s focus.
Research indicates that models prompted to adopt a professional persona are statistically more likely to identify subtle linguistic cues, such as a speaker correcting themselves mid-sentence. When a model is "primed" to expect ambiguity, it is significantly more likely to prioritize later, corrective statements over initial, superseded information. This reduces the frequency of "first-mention bias," where the model favors the earliest piece of information it encounters.
Strategy 3: Dynamic Few-Shot Demonstration Selection
Few-shot prompting—providing the model with examples of desired input-output pairs—is a cornerstone of modern LLM performance. However, a common mistake is the inclusion of redundant examples. Simply adding more examples does not guarantee better performance; it can, in fact, lead to overfitting or bias.
To optimize this, engineers are increasingly using vector-based similarity metrics, such as cosine similarity via TF-IDF or embedding models, to ensure that demonstrations are diverse. By selecting examples that represent distinct "failure modes"—such as a case with a confirmed owner, one with an unresolved owner, and one involving task merging—the developer provides the model with a broader conceptual map of how to handle complexity. This diversity-aware selection ensures the model learns the logic of the task rather than merely mimicking a single, repetitive pattern.
Strategy 4: Implementing Chain-of-Thought Reasoning
Chain-of-thought (CoT) prompting requires the model to articulate its reasoning process before delivering a final result. While frontier models are increasingly capable of internal reasoning, explicitly requesting a step-by-step trace remains essential for highly ambiguous tasks.
In the case of the meeting transcript, a CoT prompt might instruct the model to: "Trace the assignment of each task throughout the conversation before finalizing the output." This forces the model to maintain a "working memory" of the conversation, preventing it from latching onto the first assignment mentioned. For organizations concerned about the increased token usage associated with CoT, "Chain of Draft" techniques—where the model provides truncated, five-word summaries of its reasoning—have been shown to retain significant accuracy while reducing latency and computational costs by over 90%.
Strategy 5: Automated, Iterative Prompt Optimization
The final and most advanced tier of prompt engineering is the transition from human-led tuning to automated, scored optimization. This involves creating a test suite of "ground truth" examples and using a hill-climbing search algorithm to identify which specific instructions actually improve the output.
In an automated optimization loop, the system evaluates candidate prompts against a composite score that measures recall, owner accuracy, and a penalty for "hallucinated" or fabricated items. By testing thousands of permutations, the system can discover the "minimum effective instruction set." Data from recent internal tests suggest that this method often identifies a combination of three highly specific rules that outperform a bloated, manually crafted prompt containing ten or more generalized instructions.
The Broader Implications for AI Infrastructure
The move toward rigorous prompt optimization signifies the professionalization of AI operations (AIOps). As companies shift away from the "prompting as an art" mindset, they are adopting the scientific method: formulating a hypothesis, testing against a ground-truth dataset, measuring the results, and iterating based on empirical data.
The implications for the broader economy are substantial. If organizations can reduce the error rate in automated data extraction by even 10% through these optimization techniques, the cumulative efficiency gains in administrative, legal, and software development sectors would be massive. Currently, most AI failures in the enterprise are not due to model capability but to inadequate "instructional alignment."
Conclusion: From Intuition to Engineering
The current state of prompt engineering is at an inflection point. The era of "guessing" at what makes a prompt work is being replaced by systematic, data-driven engineering. By prioritizing structured output, utilizing diversity-aware few-shot examples, and employing automated optimization, developers can bridge the gap between a chatbot that "seems to work" and a system that functions with the reliability of traditional software.
Ultimately, the goal of these strategies is to ensure that LLMs serve as reliable components of a larger architecture. Whether it is an executive assistant summarizing meetings or a backend service processing invoices, the demand for precision is universal. The path to achieving this precision lies in moving away from anecdotal fixes and toward a standardized, measurable, and repeatable framework for prompt optimization. As the industry continues to mature, those who treat prompt optimization as a rigorous engineering discipline rather than a creative exercise will be best positioned to harness the full potential of large-scale generative models.