The landscape of large language models (LLMs) has reached a critical inflection point where raw parameter counts and benchmark supremacy are yielding to the more pragmatic demands of production-grade efficiency. With the release of DeepSeek-V4.1-Flash, the research organization DeepSeek has signaled a shift in strategy, moving away from the "bigger is better" paradigm toward an architecture explicitly designed to solve the bottlenecks inherent in long-running AI agent operations. By optimizing for prefill costs, memory bandwidth, and the persistent state of agents, DeepSeek-V4.1-Flash represents a significant departure from standard decoder-only transformer architectures.
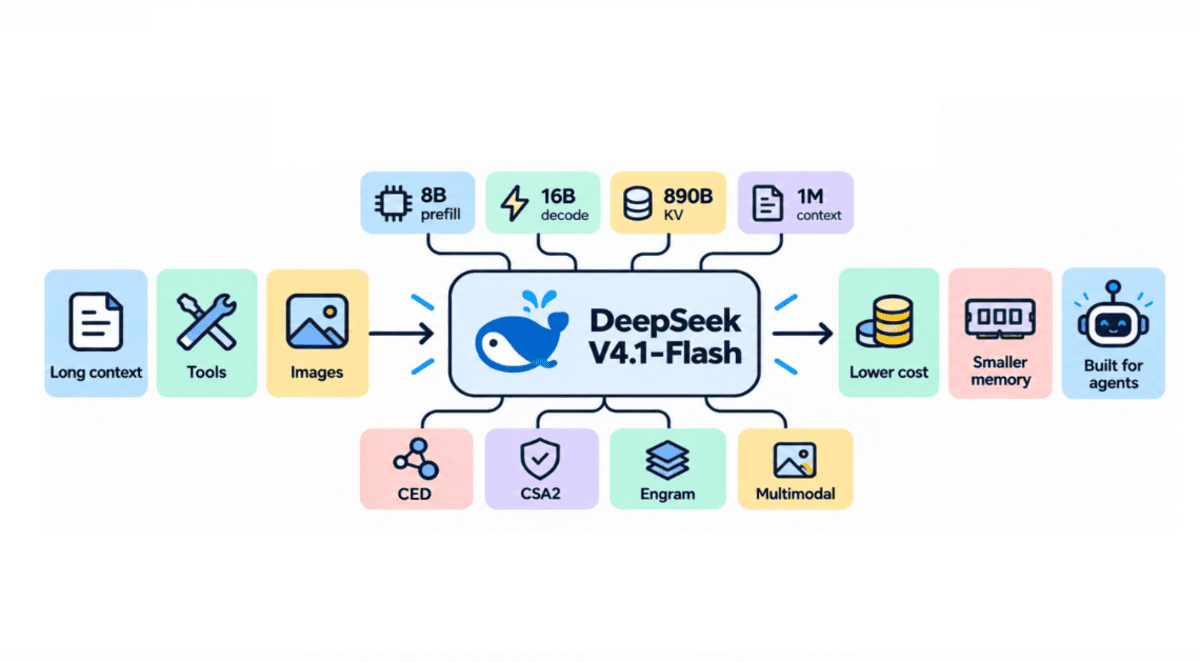
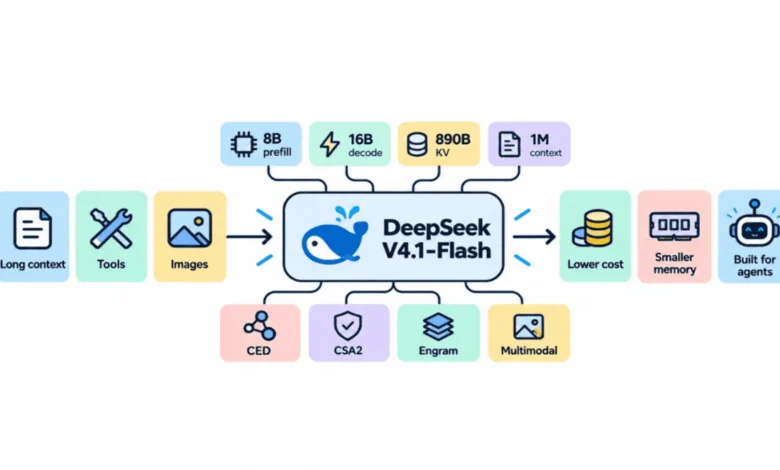
The model, which features 552 billion parameters, employs a sophisticated Mixture-of-Experts (MoE) structure that dynamically scales its active parameters based on the phase of inference. By activating only 8 billion parameters during the prefill stage and 16 billion during decoding, the model achieves a compute-efficient profile that mirrors the realities of modern agentic workflows, where systems frequently ingest massive amounts of context data before generating concise, targeted responses.
Architectural Innovations and the Shift in Inference Paradigms
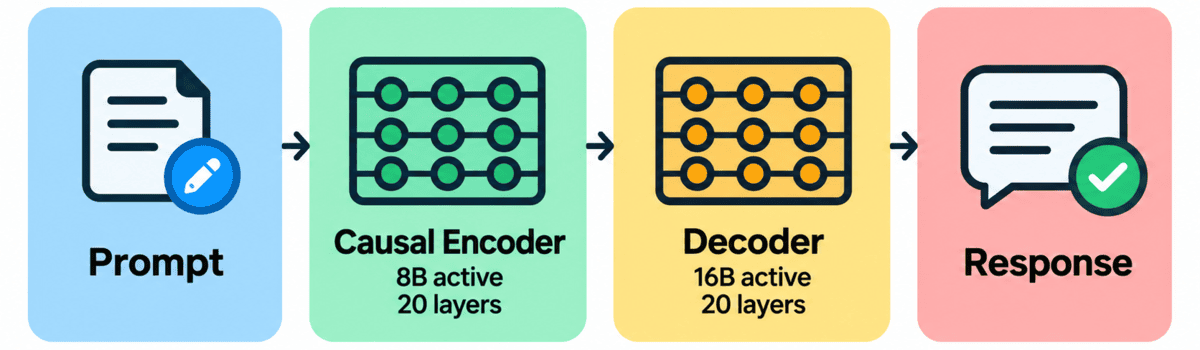
The primary innovation powering DeepSeek-V4.1-Flash is the Causal Encoder-Decoder (CED) architecture. Unlike traditional Transformers that rely on a unified decoder structure, the CED approach separates the ingestion of input data from the generation of output. By utilizing a 20-layer causal encoder followed by a 20-layer decoder, the model decouples the computational load. During the prefill phase, the encoder processes the prompt, and the decoder draws upon these pre-computed global Key-Value (KV) representations rather than recalculating them independently at every layer.
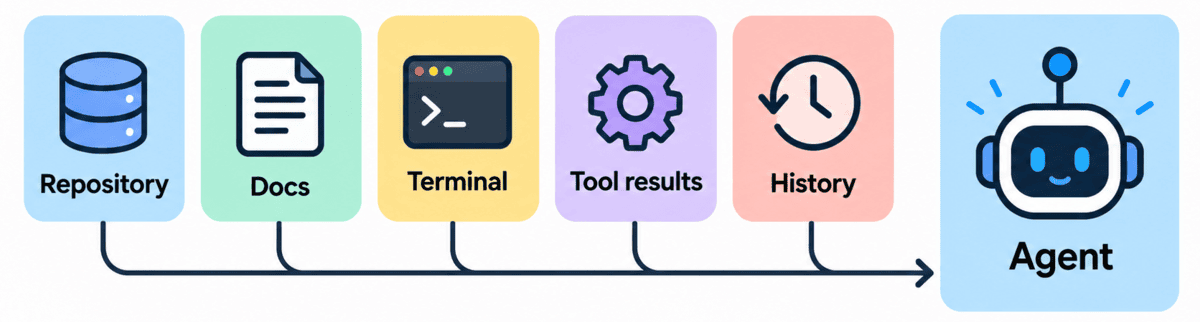
This design choice addresses a major economic hurdle in LLM deployment: the high cost of processing long input prompts. For developers building coding assistants or automated research agents, the cost of processing thousands of lines of code or extensive documentation often exceeds the cost of generating the final output. By reducing active parameters during the prefill phase to 8 billion, DeepSeek-V4.1-Flash offers a lower-latency, lower-cost alternative to models that treat every token with the same computational intensity.
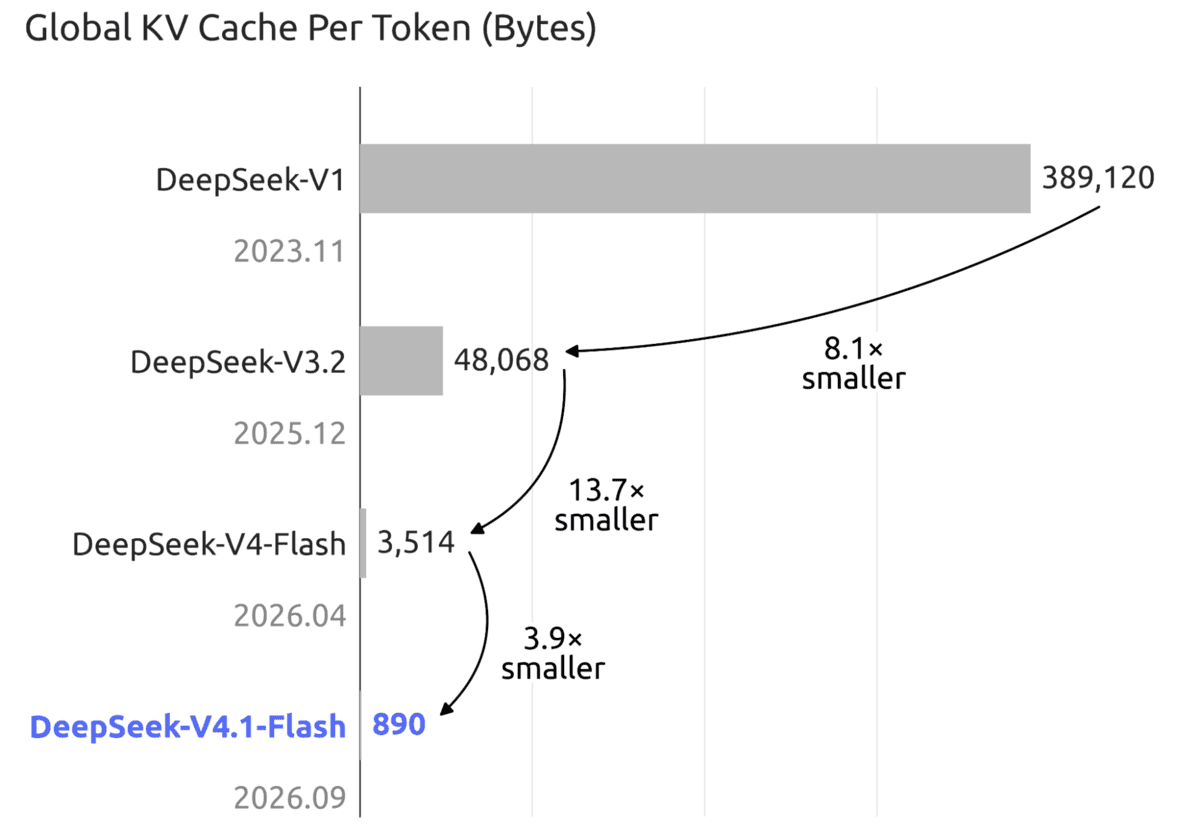
Furthermore, the model’s approach to memory management through Compressed Sparse Attention 2 (CSA2) marks a substantial advancement. As context windows scale toward the 1-million-token mark, the KV cache becomes the primary source of memory exhaustion. Through a combination of "Full," "Reindex," and "Reuse" attention modes, the model effectively minimizes redundant computation across layers. This, combined with FP4 KV caching and SWA Bounded Replay, brings the global KV cache requirement down to a highly optimized 890 bytes per token. For an enterprise deploying agents at scale, this reduction in memory footprint—approximately one-quarter of the requirement of its predecessor—directly translates to higher throughput and lower infrastructure overhead.
The Role of Engram Conditional Memory
Beyond its backbone architecture, DeepSeek-V4.1-Flash integrates a 196-billion-parameter "Engram" component. This is not a dense layer that fires for every token; rather, it functions as a sparse, conditional-memory retrieval system. In biological terms, an engram is a unit of cognitive information imprinting; here, it allows the model to "lookup" specialized knowledge without forcing the entire 552-billion-parameter backbone to process the request.
This mechanism is particularly beneficial for tasks requiring deep domain knowledge—such as cybersecurity diagnostics or complex software debugging—where the model must navigate vast repositories of information without incurring the latency penalty of a full-model forward pass. This hierarchical approach to memory reflects a broader trend in the industry toward architectures that behave more like integrated database-and-inference engines rather than static, monolithic black boxes.

Empirical Performance and Agentic Capabilities
When evaluating the model against industry-standard benchmarks, the results demonstrate that these architectural trade-offs do not come at the expense of capability. In fact, in several agent-focused categories, DeepSeek-V4.1-Flash outperforms its predecessors and competes strongly with the current state-of-the-art.
In the DeepSWE v1.1 benchmark, which measures an agent’s ability to navigate complex software engineering tasks, the model achieved a score of 74.2, significantly higher than the V4-Pro and V4-Flash iterations. Similarly, in Terminal-Bench 2.1 and CyberGym, the model demonstrated robust proficiency in executing shell commands and identifying security vulnerabilities. These benchmarks are crucial because they measure the "agentic loop"—the ability of an AI to interact with external environments, observe feedback, and iterate on its strategy—rather than simple text completion.
| Benchmark | V4-Flash | V4-Pro | V4.1-Flash |
|---|---|---|---|
| DeepSWE v1.1 | 54.4 | 62.7 | 74.2 |
| Terminal-Bench 2.1 | 82.7 | 87.9 | 90.6 |
| CyberGym | 76.7 | 83.3 | 88.1 |
| AutomationBench | 37.7 | 43.2 | 54.8 |
| Agent’s Last Exam | 25.2 | 25.7 | 31.8 |
The consistent improvement across these metrics suggests that the architectural changes—specifically the efficiency gains in input processing and the hierarchical sparse indexing—allow the model to maintain focus on the objective even when dealing with extremely long context windows.
Broader Implications for the Open-Source Ecosystem
The decision to release DeepSeek-V4.1-Flash under the MIT license is perhaps as significant as the technical specifications of the model itself. In the current AI climate, where many leading models are guarded behind proprietary APIs and "black box" constraints, DeepSeek’s transparent documentation of its inference stack serves as a catalyst for innovation.

By publishing the implementation details of its Single-Pass mHC (Memory-efficient Heterogeneous Computation) and DSpark speculative decoding techniques, DeepSeek is effectively handing a blueprint to the open-source community. These methods address the "memory wall"—the physical limitation of how fast data can move from memory to compute units—which is currently the most pressing constraint in AI deployment. As developers integrate these techniques into existing inference frameworks like vLLM, TGI, or custom local-deployment engines, the standard for what constitutes an "efficient" model is likely to rise.
The implications for the industry are twofold. First, it democratizes the ability to run high-intelligence, agentic models on constrained hardware. Second, it shifts the focus of AI research from purely algorithmic accuracy to system-level integration. Future iterations of open-source models will likely be expected to provide similar transparency regarding KV cache management, conditional memory, and prefill/decode efficiency.

Conclusion and Future Outlook
While DeepSeek-V4.1-Flash may not claim the absolute top spot in every leaderboard, its value proposition is distinct. It represents a pivot toward the engineering requirements of the next generation of AI: agents that must act in real-time, process massive context windows, and operate under strict latency and memory budgets.
The research community’s response to this release will be critical. If these architectural features, such as the asymmetric prefill-decode compute and the Engram memory, prove as scalable as they appear, they will likely become standard features in the next cycle of foundational models. As the industry moves past the initial excitement of large-scale pretraining, the focus is shifting toward the sustainable, efficient operation of these systems in real-world environments. DeepSeek has provided not just another model, but a compelling new direction for how those systems can be constructed.