
services
-
Cloud Analytics
Build RAG-ready indexes from Amazon S3 with Amazon OpenSearch intelligent ingestion | Amazon Web Services
The launch of Amazon OpenSearch intelligent ingestion within Amazon OpenSearch Serverless (NextGen) represents a fundamental shift in this paradigm. By…
Read More » -
Machine Learning
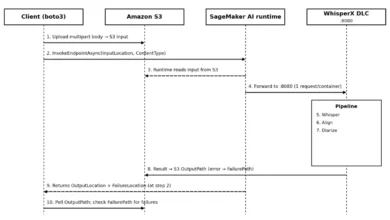
Amazon Web Services Expands Generative AI Offerings with Launch of WhisperX Deep Learning Container on SageMaker AI
Enterprises handling large volumes of spoken audio have long struggled with the limitations of generic speech-to-text transcription services. Standard automated…
Read More » -
Python for Data
Reuven Lerner Expands Technical Advisory Services Through Formalized One-on-One Python Coaching Initiatives
The landscape of professional software engineering is increasingly defined by the complexity of distributed systems, the nuance of legacy codebases,…
Read More » -
Machine Learning
Amazon Web Services Adds Moonshot AI Kimi K3 to Amazon Bedrock as the First Open Model to Reach 2.8 Trillion Parameters
Amazon Web Services (AWS) has announced the integration of Moonshot AI’s Kimi K3 into Amazon Bedrock, marking a significant milestone…
Read More » -
Machine Learning
Amazon Web Services Delivers 13 Major Inference Capabilities Across SageMaker AI to Streamline Production Generative Models
Operating generative artificial intelligence models in production environments presents a uniquely complex set of infrastructure challenges. Unlike traditional software services,…
Read More » -
Machine Learning
Introducing Kimi K3 on Amazon Bedrock | Amazon Web Services
The landscape of enterprise artificial intelligence deployment is undergoing a fundamental economic shift, driven by rapid advancements in open-weight models…
Read More » -
Machine Learning
Amazon Web Services Integrates Moonshot AI Kimi K3 as the First 2.8 Trillion Parameter Open-Weight Model on Amazon Bedrock
The global artificial intelligence landscape shifted significantly as Amazon Web Services (AWS) announced the official integration of Kimi K3, developed…
Read More » -
Cloud Analytics
Every team is a data team — bring Amazon Redshift analytics to ChatGPT Work | Amazon Web Services
Amazon Web Services (AWS) has officially launched the AWS Data Analytics plugin, a significant integration designed for the newly unveiled…
Read More » -
Cloud Analytics
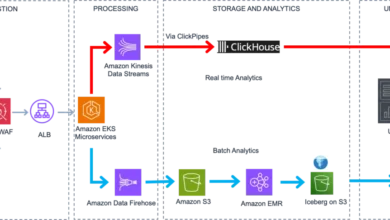
How Sony LIV built real-time video streaming analytics with AWS | Amazon Web Services
The Shift from Batch to Real-Time: A Strategic Necessity For years, streaming platforms relied on batch processing, where data logs…
Read More » -
Machine Learning

Amazon Web Services Introduces Model Caching for Amazon SageMaker Inference on HyperPod to Eliminate Cold Start Latencies for Large Language Models
The deployment of massive large language models (LLMs) for enterprise production environments has long faced a significant operational hurdle: the…
Read More »